
Prototype to production means proving the system survives real users, real data, and failure, not just proving the idea works. Harden when the shortcuts sit in code, rebuild when they run through the architecture, and retire the prototype when validation itself quietly failed.
Prototype to production means proving the system survives real users, real data, and failure, not just proving the idea works. Harden when the prototype’s shortcuts sit in code, rebuild when they run through the architecture, and retire the prototype when validation itself quietly failed.
The application-development manager and the enterprise architect usually meet this problem after the fact. A team built something to test an idea, the idea held, and a department started depending on the result. The prototype now carries real records, real decisions, and a growing user list, and the questions arriving from security, operations, and audit are questions it was never built to answer.
This page owns the transition: what a working prototype still needs before an enterprise can depend on it, in what order to close the gaps, and how to decide whether the prototype gets hardened, rebuilt, or set aside. It does not own the decision to prototype in the first place, the definitional question of what a prototype is, which platform a rebuild should target, or the separate problem of an application that has already run in production for years: each of those has its own home.
The route this page addresses is not a decision but a drift. Nobody decided to go to production; the demo became the system while everyone was busy agreeing it was useful. The qualities that made the prototype persuasive (speed, focus, a small honest scope) are the ones that make it fragile under load it was never scoped for.
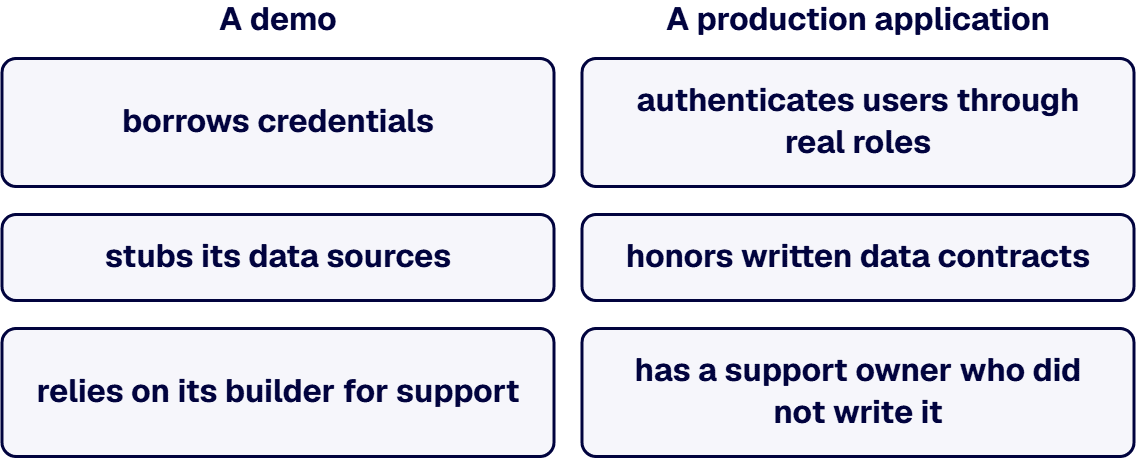
A proof of concept in production is not a delivery failure by itself; running one without knowing which readiness domains it skipped is. A prototype earns its keep by ignoring things on purpose: it handles the happy path and skips the exceptions, it uses its builder’s credentials wherever real provisioning would slow the week down, it points at a copy of the data or a stub of the interface, and it gets supported by the one person who wrote it. Each shortcut was correct for the prototype’s job, which was to answer a question about value, and each becomes a liability the day the answer is yes.
The gap is intent, which is why prototype versus production is a poor argument to settle by code quality alone. Clean code with no owner, no monitoring, and no rollback path is still a prototype. It works until it does not, and the day it does not is the first day anyone asks who owns it.
A production-ready application is one where a named person can answer the core question in each domain from a record rather than from memory. The domains are not a maturity ladder; they are a checklist of decisions a prototype may skip by design.
| Domain | Core question | First test |
|---|---|---|
| Business ownership | Who accepts outcomes, rules, and changes? | A written acceptance from the owner, filed with the backlog |
| Architecture and data | Does the design carry real users, real volumes, and the systems it touches? | A written data contract per stubbed integration, plus a load test at production-shaped volumes |
| Security and identity | Are access, roles, secrets, retention, privacy, and regulatory obligations production appropriate? | A credential inventory naming where each secret lives, unknowns listed |
| Quality and testing | Has the system met real process, real data, and failure behavior? | A test plan run on production-shaped data, failure cases included |
| Lifecycle and release | How do changes deploy, roll back, and get tracked? | A rollback rehearsed in non-production, timing written down |
| Operations and support | Who sees failures, resolves them, and restores service after data loss? | An alert fired on purpose that reached a person who acted, plus a restore rehearsed from backup |
| Adoption and change | How do users transition and keep working? | A pilot group doing real work, their issues logged |
Every first-test cell names an artifact and the surface that produces it. An inventory with explicit unknowns and a named owner accepting the residual risk is valid evidence; “we reviewed everything” is not, because it cannot be checked.
Security is the domain where prototype shortcuts age worst. A prototype started inside stage gates, with roles provisioned from day one, begins ahead; one built outside them authenticates as whoever built it until someone changes that. Data retention, privacy, and regulatory obligations sit here too, not in a later compliance phase. The first hardening moves are unglamorous: real roles instead of a shared account, and secrets out of source code and configuration files.
Data contracts are the architecture domain’s version of the same discipline. A prototype that reads a spreadsheet export or a stubbed interface has an informal agreement with its data sources, enforced by nobody. A data contract makes that agreement explicit: what shape the data has, what each field means, which system is the source of truth, and who owns a change to any of it. Writing one per integration is slow exactly where the prototype was fast, and it is where most hidden production risk surfaces, because the exceptions the prototype skipped live in the real data. i3solutions designs and builds applications on the Microsoft stack with the architecture decided first, the scope defined, and the delivery owned by senior engineers.
Custom Application Development with Enterprise Accountability
The prototype had no error handling because failure was never its subject: when a call timed out during the demo, someone refreshed the screen and kept talking. Production reverses the emphasis. The interesting question stops being what the system does when everything works and becomes what it does when the network drops mid-transaction, when the upstream system sends a malformed record, and when two users edit the same thing at once.
Testing for production has to include those cases on production-shaped data, with results recorded against acceptance criteria the business owner agreed to in advance. Enthusiastic users are evidence of value, and they are not acceptance testing; the difference is a written criterion and a recorded result. For systems that will carry regulated records or money, independent validation earns its cost: someone who did not write the code confirms what it does under failure before the business depends on it. The review itself is described in Enhancing Quality With an IV&V Code Review.
A prototype deploys by whoever built it copying files, which is fine until the first bad change lands in front of real users with no way back. Lifecycle and release discipline is the difference between a bad change costing minutes and costing a weekend. Approval gates need owners who actually respond, and staging environments let a team validate a build before it reaches production.
Tools do not make the discipline. The release domain is closed when a rollback has been rehearsed in a non-production environment and the timing is written down, because a rollback nobody has rehearsed is a plan on paper. The rehearsal is the producible artifact; the pipeline is just where it runs.
An unwatched system fails silently, and a prototype is unwatched by default. Observability means the system reports on itself: what failed, where, and for whom, visible to someone whose job includes looking.
The support model is the human half of the same domain. Production support requirements come down to names: who a user calls, who triages, who can change code, and who decides when to take the system down. While the builder answers all four, the organization has a single point of failure with a vacation schedule. A runbook, an escalation path, and a support owner who is not the original developer are the artifacts that close this domain. Recovery belongs here too: backup, a proven restore, and the recovery time and recovery point the business accepts.
Adoption is the domain teams skip because the pilot users needed no training, forgetting that pilot users are volunteers. The wider population inherits none of their patience. Rollout requirements are modest but real: training material, a communication plan, a feedback route, and a cutover decision that says when the old way of working actually stops.
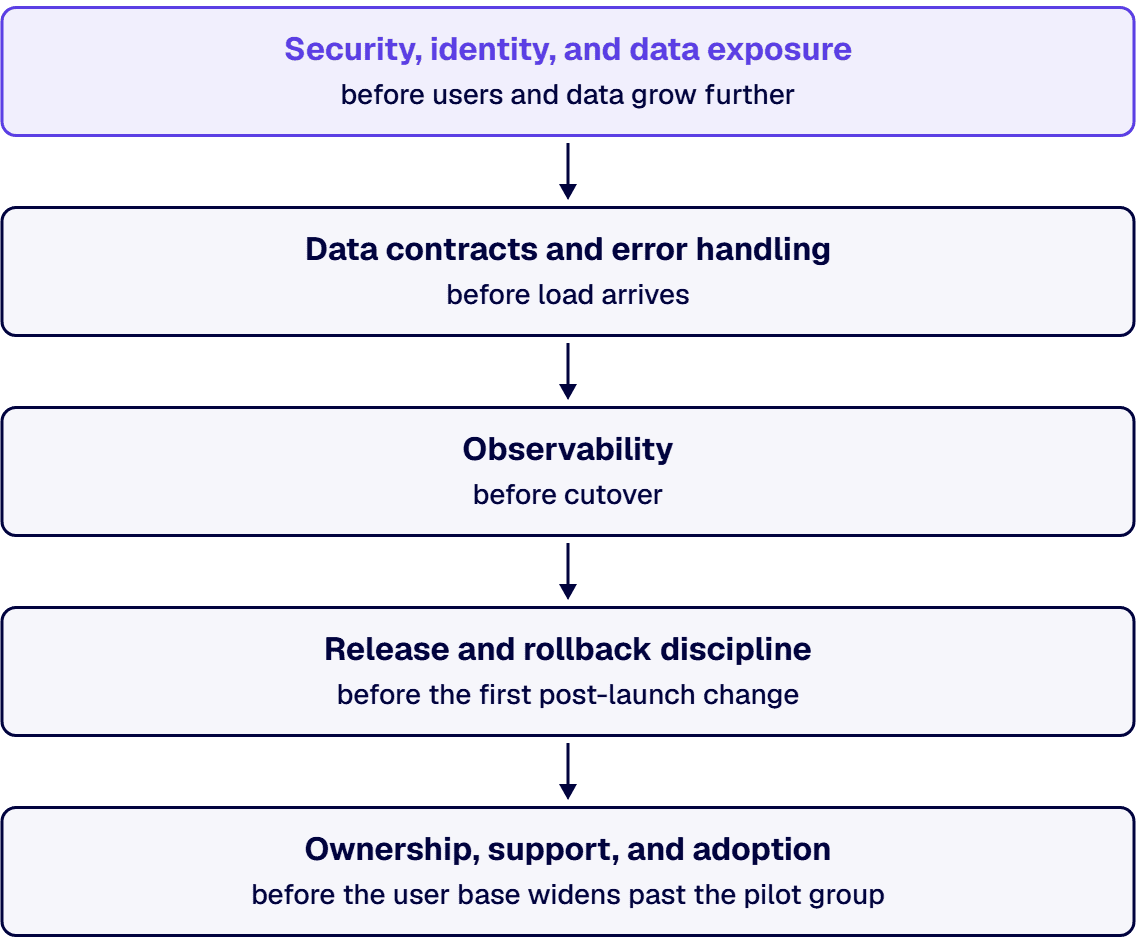
Order the work by consequence, not by convenience. Security, identity, and data exposure close first, before users and data grow further, because these are the gaps where harm compounds while you work on other things. Data contracts and error handling come second, before load arrives, since both get more expensive to retrofit as usage grows. Observability comes third and specifically before cutover, because cutting over without it means learning about failures from users. Release and rollback discipline closes before the first post-launch change, not after it. Ownership, support, and adoption close before the user base widens past the pilot group.
What never drives the order is ease. Closing the cheapest gap first feels like progress and leaves the exposure the page opened with (a system holding real data behind prototype credentials) standing while the easy work gets done.
The call on an existing prototype comes down to where the shortcuts live. Shortcuts in code (missing error handling, hard-coded credentials, absent tests) are repairable in place: hardening keeps the validated behavior and pays down the skipped domains one at a time. Shortcuts in architecture (a data model that cannot carry the real volumes, a platform that cannot meet the security or integration requirements, a design that assumed one user where hundreds are coming) do not harden out.
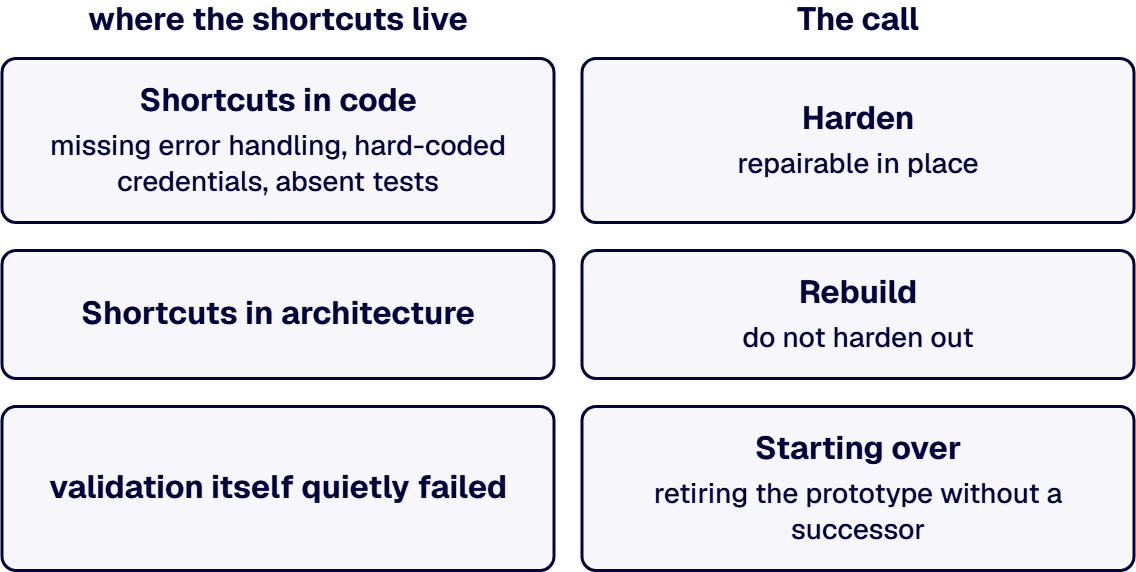
Price both paths against the framework. Walk the seven domains and ask whether each gap closes by adding to what exists or by replacing it. When most answers are additions, harden. One blocker outranks the count: a replacement-class answer in security, compliance, or data integrity makes it a rebuild question however many answers are additions. A rebuild also reopens the platform question, which deserves its own decision rather than an inherited assumption.
Starting over (retiring the prototype without a successor) is the honest answer when validation itself quietly failed: usage never grew past the pilot group, or the process the prototype served is being absorbed by a platform the organization already owns. A prototype that taught the organization not to build the system did its job.
User enthusiasm gets treated as acceptance testing, so the first real acceptance test happens in production. The prototype’s credentials and data connections come along to production because they already work. The original developer stays the only owner, unnamed in any support model, until the day they change jobs. Rollback is a plan on paper that has never been rehearsed, discovered to be fiction during the first bad release. Reporting, exceptions, and integration needs that the prototype skipped get discovered by the departments that needed them, after cutover. Training is deferred until after launch on the theory that the system is intuitive, a theory the pilot volunteers were never in a position to test.
Some of these failures have a technical face, and all trace back to a readiness domain never assigned to a person, which is why the framework asks who before it asks how.
If the prototype has not yet proven its value, the next call is validation, not hardening: finish the experiment first. If the need is a commodity workload a packaged product already covers, buy the product and spend the delivery budget elsewhere. If your estate and your team are committed to a non-Microsoft stack, a partner who lives on that stack will serve the rebuild better. And if the honest reading of the framework says retire, the right spend is a decent export of the data, not a services engagement.
Michael Branson co-founded i3solutions 30 years ago and brings executive, operational, and technical perspective to organizations working in complex, secure, and mission-critical environments. His insights focus on business process consulting, automation, data analytics, collaboration, secure operating models, and the operational discipline required to turn technology investments into practical business systems with measurable value.
Connect on LinkedInClose seven domains, each with a named owner and a producible artifact: business ownership, architecture and data, security and identity, quality and testing, lifecycle and release, operations and support, and adoption and change. Sequence the work by consequence: the security, identity, and data exposure gaps first, then data contracts and error handling, then observability before cutover, then release and rollback discipline before the first post-launch change, then ownership, support, and adoption before the user base widens past the pilot group. The safest transitions are boring. Each domain closes with evidence a third party could check: an owner acceptance in writing, a credential inventory, a recorded failure-case test, a rehearsed rollback, an alert that reached a person, and a pilot group's logged issues. Where the prototype already carries production load, the order holds and rollout gates replace cutover.
Intent, not code quality. A demo, like the prototype behind it, is built to answer a question about value: it skips exceptions, borrows credentials, stubs its data sources, and relies on its builder for support. A production application is built to survive failure. It authenticates users through real roles, honors written data contracts, and handles the malformed record and the dropped connection. It deploys through a release process with a rehearsed rollback, reports on itself through monitoring, and has a support owner who did not write it. Clean code with no owner, no monitoring, and no rollback path is still a prototype.
Locate the shortcuts. Shortcuts in code, missing error handling, hard-coded secrets, absent tests, thin logging, are repairable in place, and hardening preserves behavior that real use has already validated. Shortcuts in architecture do not harden out. A data model that cannot carry production volumes, a platform that cannot meet security or integration requirements, or a single-user design facing hundreds of users calls for a rebuild. Keep the prototype as a validated statement of requirements. Walk the seven domains and ask whether each gap closes by adding to what exists or replacing it. Mostly additions means harden; architecture-level replacements mean rebuild; a replacement-class answer in security, compliance, or data integrity outranks the count. A rebuild also reopens the platform choice, which deserves its own decision rather than an inherited assumption. If validation itself quietly failed, retiring the prototype is the correct outcome, not a defeat.
A named person able to answer each domain's core question from a record. On the technical side: what architecture and data contracts the application runs on, how access and secrets are controlled, and what testing evidence exists against agreed criteria. On the operating side: who owns the system and its changes, how releases deploy and roll back, who monitors and supports it, and how users were trained and cut over. Readiness is a set of decisions with owners, not a final testing stage.
Not the original developer alone, and that answer is the point. A production support model names a first contact for users, a triage owner, an escalation path to people who can change code, and an authority who decides when the system comes down. The original developer can hold one of those roles; while they hold them all, the organization carries a single point of failure with a vacation schedule. The runbook, the escalation path, and a support owner outside the build team are the artifacts that make support real, and writing them before cutover is far cheaper than writing them during the first outage.
Failing tools, prototypes in production, and applications past their platform's design space migrate on your schedule or on a deadline an outage picks. i3solutions' senior application architects work with IT leaders ready to scope the build deliberately.
Schedule an Application Scoping Discussion
US-Based | Est. 1997
© i3solutions. All rights reserved.
US-Based | Est. 1997
© i3solutions. All rights reserved.


