
Copilot pilot vs enterprise rollout is a sequencing question, not a fork: a pilot earns the rollout by producing evidence of task fit, sustained use, and governance that held. Expand into roles whose work resembles the pilot role.
The question arrives in a specific shape. Finance approved a block of licenses. Two hundred went out to volunteers across eleven departments. Six months later the steering committee wants to know whether to buy three thousand more, and the only evidence in the room is a survey, a demo everyone remembers, and an activity chart nobody trusts. That is not a pilot. It is a distribution, and it answers no question the committee is asking, because nothing in it was designed to produce an answer.
A pilot is an experiment with a stated hypothesis, a bounded population, a fixed observation window, and exit criteria written before the first license lands. Microsoft’s own deployment guidance sets the shape plainly in Set up Microsoft Copilot and assign licenses, which names three phases, Pilot, Deploy, and Operate, and defines the first one as assigning licenses to a small group of users to test the deployment and gather feedback. This page is about what “test” has to mean before “Deploy” is a defensible signature.
This page owns one decision and its evidence: whether the pilot result you now hold justifies expanding Copilot, and to whom, in what order. Four decisions that arrive before this one belong to other pages, and the split matters because different people make them.
Whether your tenant is in a state where turning Copilot on is safe is a readiness decision with its own gates, worked in full in Is Your Microsoft Environment Ready for Copilot? What Must Be True First. This page assumes that decision is already made and does not restate its gates. If the blocker is permission debt, an overshared estate, or a security team that stopped the project, the remediation sequence and its exit criteria are the subject of The Copilot Data Governance Fix, and no pilot design substitutes for it. What the licenses cost, how base-plan posture drives that cost, and when a purchase should wait are set out in Microsoft 365 Copilot Licensing: What a Governed Enterprise Deployment Actually Costs; this page decides the shape of the expansion, not its price. And the risk profile of skipping the governed path entirely is compared side by side in Secure Copilot Enablement vs Turn It On: The Enterprise AI Risk Comparison.
What remains, and what no other page on this site owns, is the adoption path: cohort selection that produces evidence, use-case selection before license expansion, success metrics agreed before launch, and the decision the window has to produce.
Design the pilot so that a negative result is a real possibility, because a pilot that cannot fail produces no information. A pilot that gives licenses to enthusiasts, runs for an unbounded period, and ends when someone writes a summary has already decided its own outcome.
Three claims are worth testing, and a pilot that returns clean on the first two and dirty on the third has still done its job.
The first claim is task fit. Not “people liked it” but “this named task, done this many times a week by this role, got faster or better, and the person doing it would object if the license were withdrawn.” Task fit is claimed per role, never per company, because the tasks differ per role.
The second claim is sustained use. First-week usage measures curiosity. What predicts an expansion worth funding is whether the same people are still using the same features in week eight, after the novelty is gone and the training session is a memory.
The third claim is that the governance held. During the window, someone reads the Copilot interaction record Microsoft Purview surfaces from audit log data, and confirms it answers a question asked after the fact. This claim is the reason the pilot cohort works inside a cleared zone while the rest of the tenant waits. Microsoft states that Copilot only surfaces organizational data to which individual users have at least view permissions, so the pilot’s exposure is the cohort’s effective access across Microsoft 365.
One thing a pilot does not have to re-prove is Microsoft’s own data commitment: Data, Privacy, and Security for Microsoft Copilot states that prompts, responses, and data accessed through Microsoft Graph aren’t used to train foundation LLMs. Record the citation once and move on; the pilot’s governance question is about your permissions and your labels, which that commitment does not speak to.
Write the exit criteria into a one-page charter before a single license is assigned, and have the person who would sign the expansion sign the charter first. A criterion invented after the numbers arrive is a rationalization wearing a criterion’s clothes.
An assistant that answers well is not yet an assistant you can defend. i3solutions’ AI services put the exposure mapping, controls, and audit evidence around Microsoft AI so the deployment survives the review that follows it.
The default cohort is volunteers, and volunteers answer a different question than the expansion decision asks. They self-select for enthusiasm, they work around friction and leave it unreported, and their result does not transfer to the people who will receive the next three thousand licenses.
Build the cohort on four properties instead, and check each one before the charter is signed.
One role, or two closely related roles. A cohort spread across eleven departments produces eleven anecdotes and no finding. A cohort of forty people doing recognizably the same work produces a claim about that work, and that claim is what the next expansion wave rests on.
A named task the role does weekly. Meeting recap for a role that lives in meetings; first-draft response for a role that answers the same class of question all day; document comparison where the daily work is contract review. Pick the task first, then pick the people who do it.
Data readiness already cleared for the content that cohort can reach across Microsoft 365. The pilot tests adoption, not permission debt. If the content the cohort can reach has not been through remediation, the pilot will discover permission debt instead of task fit. When one candidate role has the better weekly task and another has the cleared access, the cleared access decides.
A skeptic quota. Include people who were not asking for this. A cohort with no skeptics returns a result that expansion will not reproduce.
Size follows from what the measurement needs. The Connect to the Microsoft Copilot Dashboard for Microsoft 365 customers documentation states that to protect individual privacy, metrics aren’t shown for groups smaller than the minimum group size an organization has configured. Size the cohort against that number: forty to eighty people in a single role is a workable size once it is checked against it.
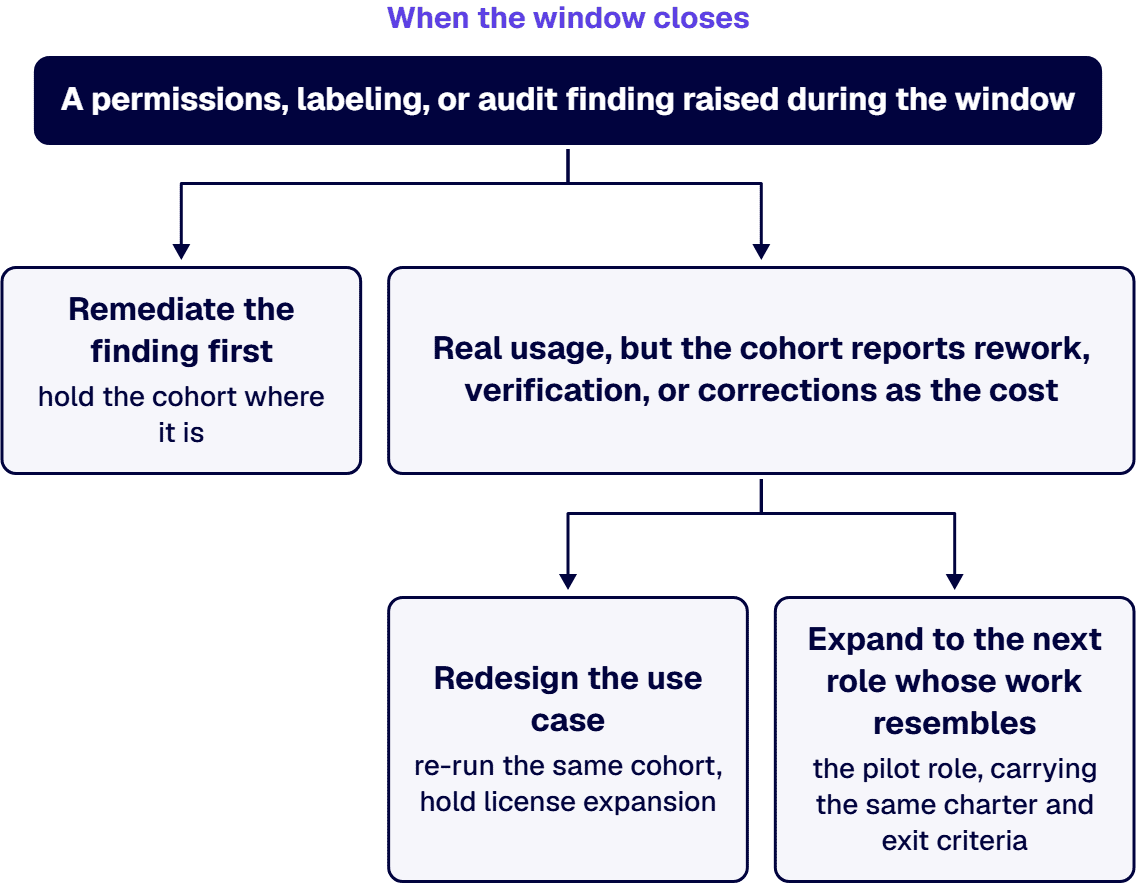
When the window closes, four readings are available, and the difference between them is what the cohort produced. A window can produce more than one of these readings, and when it does the order is fixed: the governance finding is settled first, the workflow finding next, and expansion waits behind both.
i3solutions has delivered a Microsoft 365 Copilot deployment, pilot or rollout for a client.
| What the pilot produced | The reading | The decision |
|---|---|---|
| Active users rate holding from one 28-day window to the next, a named task the cohort would defend, the governance watch raised nothing | The design works for this role | Expand to the next role whose work resembles the pilot role, carrying the same charter and exit criteria |
| Real usage, but the cohort reports rework, verification, or corrections as the cost | The product fits the task, the workflow around it does not | Redesign the use case, re-run the same cohort, hold license expansion |
| Usage falling away after the first weeks, no task the cohort would defend | The use case was chosen for the demo rather than for the work | Pause expansion, choose a different task and cohort, keep the licenses you hold |
| A permissions, labeling, or audit finding raised during the window | The tenant is the blocker rather than the pilot | Remediate the finding first, hold the cohort where it is, restart the window after |
The fourth reading is the one that gets misfiled. A pilot that surfaces an oversharing finding has succeeded: it found the problem with forty people watching instead of four thousand. Expanding anyway, on the argument that the finding is small, converts a contained finding into a tenant-wide one. The second reading is the one that gets skipped: usage is present, the cohort is not hostile, and the honest summary is that the output needs checking before it is usable. That is a workflow finding rather than a product verdict, and the response is to change where the task sits in the process instead of widening the population that inherits the rework.
Once a pilot has earned an expansion, the ordering question arrives, and the default answer is wrong. Enterprises sequence by department size, by executive interest, or by whoever asked loudest. Two properties should drive the order instead.
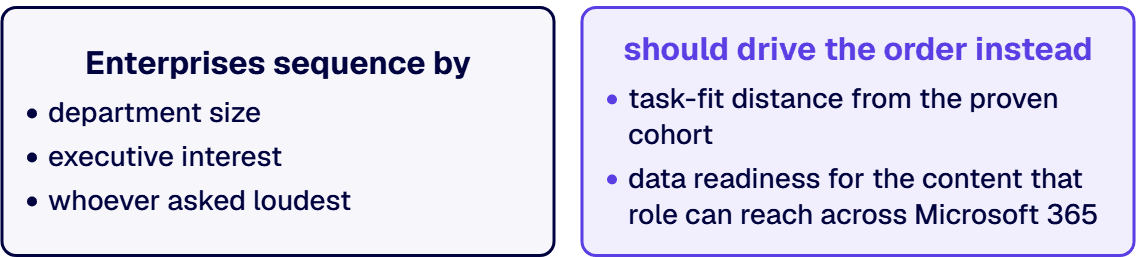
The first is task-fit distance from the proven cohort. A role whose weekly task is the same task the pilot tested, done on the same content types, inherits the pilot’s evidence. A role whose weekly task is a different one inherits the pilot’s governance result and its license-administration lessons but no part of its task-fit or sustained-use claim, and needs its own bounded window before it gets a block of licenses.
The second is data readiness for the content that role can reach across Microsoft 365. A role that works inside sites already remediated is ready now. A role whose daily work sits in the estate’s least governed corner is a remediation project first and an adoption project second. When the two properties disagree, data readiness decides the wave and task-fit distance decides the charter.
Two practical rules keep the sequence honest. Assign a license to a role only when its task claim is written down, because a seat issued without a task is the seat that shows up unused at renewal. And keep a reclaim step in the operating rhythm, so seats held by people who left the role return to the pool.
A pilot runs on attention. A rollout runs on an operating model, and the transition is where adoption programs stall. Three functions have to exist by name before the second wave, and each needs an owner who is one named person.
License administration with a written assignment rule. Microsoft’s setup guidance puts Copilot license management in the Microsoft 365 admin center and names two assignment routes: licenses go to individual users or to groups of users. The group route scales only as far as the group design behind it: a documented membership rule, a named group owner, a path for exceptions, and a check for license conflicts.
Usage measurement on a cadence, with a named reader. The instrument exists; the discipline is reading it monthly, comparing against the exit criteria the charter set, and reporting the delta to the same person who approved the expansion.
A governance handoff with a receiving owner. Once the pilot closes, the governance watch that ran inside the window becomes a standing responsibility: someone owns access reviews, agent oversight, and the audit trail from that point forward. Name the receiving owner in the expansion decision, in writing, on the day the decision is made.
Pilot fatigue has a mechanism, and it is repeatable enough to name: no exit criteria, so no exit; a cohort chosen for goodwill, whose enthusiast results do not transfer; seats issued ahead of the decision, which become the argument that the question is already settled; a use case chosen because it demos well rather than because the role’s weekly workload contains the task; and a pilot owner who leaves before anyone inherits the charter. Each of those has the same cure, applied before launch: a written charter that names the cohort and the task, a named decision-maker, a bounded window, and a decision that gets made on the date it was scheduled for, including the decision to stop.
Some organizations reading this should not be designing a pilot at all. If your tenant has not been through readiness, a pilot will surface permission debt where adoption evidence should be. If security or counsel has already stopped the project over data exposure, the remediation sequence is the work, and pilot design waits behind it. If Copilot is already live across the enterprise and the pain is agent sprawl, slipping access reviews, or an ownership gap, that is a running-program problem rather than a pilot-design problem. And if the real question is whether to buy at all, a pilot is an expensive way to relitigate a purchase decision.
What is left is the organization this page was written for: seats already bought, a first group already using them, and a steering committee that wants to know whether the next three thousand are justified by anything other than enthusiasm.
Michael Branson co-founded i3solutions 30 years ago and brings executive, operational, and technical perspective to organizations working in complex, secure, and mission-critical environments. His insights focus on business process consulting, automation, data analytics, collaboration, secure operating models, and the operational discipline required to turn technology investments into practical business systems with measurable value.
Connect on LinkedInPilot first, then expand by role, because a company-wide assignment answers no question and reverses expensively. Microsoft's deployment guidance names a pilot phase, then a deploy phase, then an operate phase, and defines the pilot as assigning licenses to a small group to test the deployment and gather feedback. The pilot's job is to produce three findings before the larger purchase: that a named task in a named role got better, that the same people were still using it weeks later, and that the governance watch raised nothing. Expansion without those three findings is a distribution rather than a rollout.
Choose the pilot cohort on four properties. Volunteering is not one of them. Pick one role, or two closely related roles, so the result transfers to the next wave. Pick a task that role performs weekly, and pick the people who perform it. Confirm the content the pilot cohort can reach across Microsoft 365 has already been through permission and labeling remediation, so the window measures adoption rather than data debt. Include people who did not ask for the license, because a cohort of enthusiasts returns a result the expansion will not reproduce. Forty to eighty people in a single role is a workable size once it is checked against the number your organization set as its minimum group size.
Four measures together, agreed in writing before launch. Active users rate, which the Microsoft Copilot usage report defines as active users divided by enabled users, tracked from one 28-day window to the next instead of as a single number. Per-user Active Days, which the same report exposes for Copilot Chat prompts and which separates a weekly habit from a monthly visit. A per-task claim from the cohort recording the task, the time before, the time after, and what changed. And the withdrawal question at the end of the window: if the license went away Monday, what would you do differently? A specific task in that answer is the qualitative half of the reading, and it counts alongside the usage numbers, not above them.
Expand when usage holds across consecutive windows, the cohort names a task it would defend, and the governance watch raised nothing. Redesign the use case and re-run the same cohort when usage is real but the cohort reports rework or verification as the cost, because that is a workflow finding rather than a product verdict. Pause expansion and choose a different task when usage falls away after the first weeks and no defended task remains. Remediate first, and hold the cohort in place, when the window raised a permissions, labeling, or audit finding.
Long enough to see behavior after the novelty fades, and short enough that the decision date holds. The tenant's usage reporting is filtered to the last 7, 28, 90, or 180 days, and two consecutive 28-day windows make a workable observation period for a reason the report does not supply: the first window carries onboarding and curiosity, and the second shows what survived them. Set the decision date when the charter is signed and keep it, because an extension granted for more data is the step that turns a bounded pilot into a permanent one. Build in the Copilot Dashboard's documented lag of up to six days when scheduling the readout.
Readiness asks whether the tenant is in a state where turning Copilot on is safe, and it is settled before pilot design starts. Pilot design asks a different question, which is whether the business value is real for a specific role and whether the evidence justifies buying more licenses. Readiness is a gate passed before the first license lands and revisited whenever the tenant changes underneath it. Pilot design is the experiment that runs after that gate is passed, and its output is an expansion decision rather than a safety decision.
A defensible AI program names its owners, its boundaries, and its evidence. i3solutions' senior AI advisors work with enterprise IT leaders who are accountable for that answer and want the governance model scoped by people who have built it.
Request an AI and Copilot Scoping Discussion
US-Based | Est. 1997
© i3solutions. All rights reserved.
US-Based | Est. 1997
© i3solutions. All rights reserved.


