
Enterprise application discovery before a rebuild produces four artifacts: a function and data inventory, a recovered business-rule register, an integration and user map, and written success criteria. Those same four artifacts are the evidence behind the choice between rebuild, replace, retire, and keep.
Enterprise application discovery before a rebuild produces four artifacts: a function and data inventory, a recovered business-rule register, an integration and user map, and written success criteria. Those same four artifacts are also the evidence behind the choice between rebuild, replace, retire, and keep.
The request usually arrives the same way. An application carrying a revenue-bearing process is failing or aging out, the person who wrote it is gone, and the documentation that survives describes the system as planned rather than as it runs. Someone asks what a rebuild would cost, and the honest answer at that moment is that no one knows yet, because what the application actually does has not been written down since the year it was written. Discovery is the work that closes that gap: an evidence-gathering exercise with a defined output, not a strategy workshop, and that output is what a scope, an estimate, and a defensible go-or-no-go decision get built from.
Discovery earns its budget by producing artifacts other people can act on. The function and data inventory answers what the application does and what it stores. The business-rule register answers why it behaves as it does: the calculations, thresholds, approval conditions, and exceptions that live in code, in queries, and in the heads of the people who work around them. The integration and user map answers what would break: the systems reading from or writing to the application, the file drops no one owns, and the roles whose daily work runs through its screens. The success criteria answer what “done” means in terms someone will sign, including the conditions under which the old system is switched off.
The inventory and the map are counted; the register and the criteria are agreed. That distinction matters at estimating time. A rebuild estimate built on the counted pair alone is arithmetic on an incomplete list. One that also carries the recovered rules and the written criteria is defensible line by line, which is what a finance committee is asking for when it asks why the number is what it is.
Each artifact is built from a different working list, and each list closes against its own test, not a general sense of completeness.
| Artifact | What it captures | The test that closes it |
|---|---|---|
| Function inventory | Screens, reports, batch routines, and functions with no menu entry | Built from the menu tree, report catalog, and job scheduler, then walked against real work by a user of each role |
| Data inventory | Tables, keys, volumes, field-level meanings, known quality defects | Row counts and key integrity from profiling queries against a restored copy; each field’s meaning confirmed by its owner |
| Integration and user map | Inbound and outbound interfaces, file transfers, roles, and who actually performs each one | Every interface confirmed by a named owner on the other side; every role confirmed by a person who performs it, not the org chart |
| Business-rule register | Calculations, thresholds, conditions, exceptions, and the source each was recovered from | Each rule traced to code, data, a named person, or a workaround, and validated against a real case |
Inventories are easy to declare finished before they are. A list of a dozen screens looks complete until someone mentions the quarter-end routine that one person runs. The user and role map is the artifact skipped first and the one that produces the most expensive late findings, because the people who use a legacy application have spent years building workarounds around its limits. Those workarounds are load-bearing. A rebuild that implements the system as designed, instead of the system as operated, ships a product that is technically correct and operationally rejected.
Spreadsheets, Access databases, and aging custom systems carry business logic that has to survive the move. i3solutions’ modernization services recover it, rebuild it, and leave your team with documentation and ownership.
This is the part buyers underestimate, and it decides whether the estimate holds. The rules that govern a long-lived application sit in four places, and each needs a different technique.
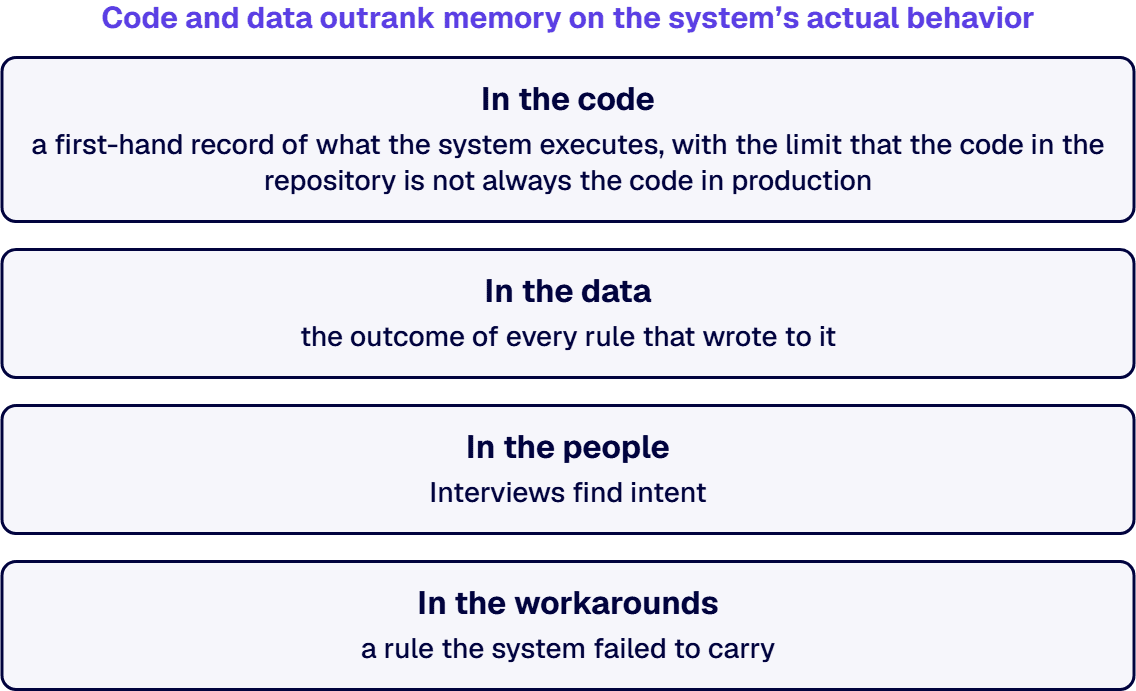
In the code. Stored procedures, form event handlers, macros, and save-time validation are a first-hand record of what the system executes, with the limit that the code in the repository is not always the code in production.
In the data. The database retains the outcome of every rule that wrote to it, which is a subset of the rules that ran. Distributions, gaps, and values that appear only under particular conditions expose logic the code no longer contains, including rules removed years ago whose historical rows still need interpreting.
In the people. Interviews find intent: why a threshold sits where it does, which exceptions are policy and which are habit. Interviews alone are unreliable, which is why each rule recovered this way is checked against real cases before it enters the register.
In the workarounds. The spreadsheet beside the application, the approval sent by email instead of through the screen, the report someone rebuilds by hand every Monday. Each is a rule the system failed to carry, and a requirement candidate for whatever replaces it.
The four sources disagree, and the register needs a rule for that case. Code and data outrank memory on the system’s actual behavior: where an interview contradicts what the code executes and the data shows, the register records the executed behavior and carries the remembered version beside it as an open question for the business owner to rule on. Where no branch in the running code produces a value the data shows, that row goes to the risk list unresolved.
A rebuild proposal contains a line for data migration, and it is priced as a transfer when it is an archaeology exercise of its own. Three questions decide the number. What does the data mean: field-level meaning drifts over a system’s life, and reconstructing it is discovery work, not migration work. What is the quality: key integrity, duplicates, orphaned rows, and dates that predate the organization, measured cheaply through profiling but decided expensively, since someone has to rule on what gets corrected, migrated as-is, or archived. What does the data owe: retention obligations, audit history, and the reports regulators expect to still run after the application is gone.
The output of this thread is a data statement: a written record of what moves, what is corrected, what is archived, and what is deliberately abandoned, with a named person signing each category. That statement is a scope boundary, and scope boundaries are what stop an estimate drifting.
Rebuild overruns are not mysterious, and they are not mostly a technology problem. Four causes recur, and discovery addresses each directly. Rules found during user acceptance testing, instead of during discovery, are a change against a scope already signed: under a fixed-scope contract, that means a new price against a schedule already committed. Integrations counted as one thing instead of several interfaces, each with its own format, schedule, failure mode, and owner, turn one line item into an unbounded one. Data cleanup deferred to migration arrives as an unplanned project inside a planned one, at the point of maximum schedule pressure. And the operating model no one documented surfaces when real users meet software that works and that the business says is wrong.
Each is cheaper to find while the scope is still open than after it is fixed, which is the case for funding discovery as its own piece of work rather than absorbing it into the opening of a build.
Discovery is not a commitment to rebuild. It is the evidence that makes the decision defensible, and the decision has more than two options. The rule register shows how much of the application’s value is bespoke logic, which is what any packaged replacement has to be tested against. The integration map shows what a retirement would strand. The user map shows whether the pain is the software or the process around it. The data statement shows what any of the paths would owe.
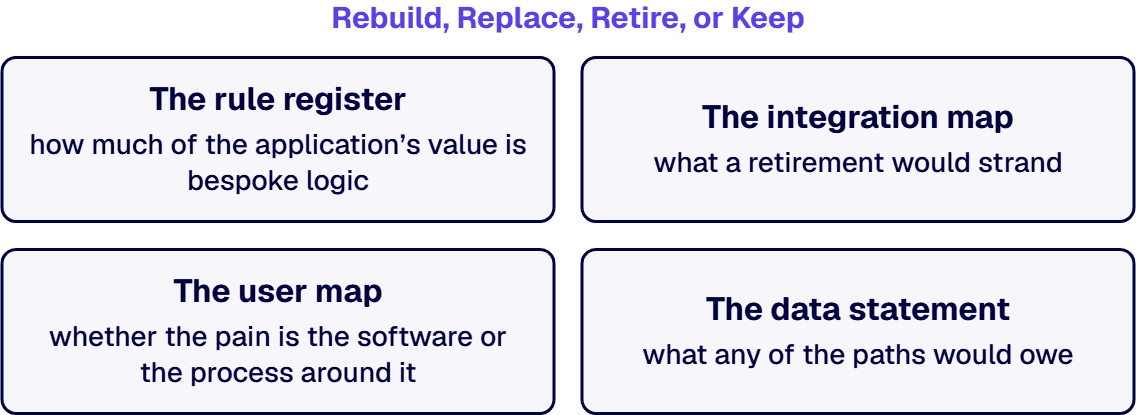
When two of those readings point at different paths, the choice is not discovery’s to make. The discovery output records the disagreement, the evidence on each side, and what it would cost to resolve, and the people who own the process decide with that in front of them.
An estimate is defensible when a stranger can read the document behind it and trace every line to a recorded fact or a stated assumption. The document set is the four artifacts, plus a data statement, a written record of what was not examined, and a risk list carrying the items discovery could not resolve, each with its likely effect on scope. A discovery report that lists no unresolved items is one to read again for what it did not reach.
Sign-off needs more than one signature. The business owner signs the function inventory, the user and role map, the rule register, and the success criteria, attesting that the system as described is the system as operated. The data owner signs the data statement, including what is deliberately abandoned. The integration owners each sign for their own interface. IT signs the data inventory, the integration inventory, and the risk list. What each signature means belongs in writing on the page above it, because “reviewed” and “attested” are different acts and only one of them holds up later.
Some readers should route elsewhere. If the destination is a Power Platform build rather than a custom rebuild, discovery is a different exercise, weighted toward process truth, data model fit, delegation limits, and licensing rather than rule archaeology. If the application is small enough that one person knows it end to end and can write the rules down without help, a discovery engagement is overhead. And if the real question is which of many systems to touch first, that is estate-level analysis, not application-level discovery.
What is left is the case this page was written for: one application that matters, a rebuild that looks likely, and no one able to say with confidence what the thing actually does. The four artifacts are the answer to that, the archaeology is the slow part, and the sign-off is what makes the estimate hold.
Michael Branson co-founded i3solutions 30 years ago and brings executive, operational, and technical perspective to organizations working in complex, secure, and mission-critical environments. His insights focus on business process consulting, automation, data analytics, collaboration, secure operating models, and the operational discipline required to turn technology investments into practical business systems with measurable value.
Connect on LinkedInFour artifacts. An inventory of functions and data recording screens, reports, batch routines, tables, and field-level meanings. A business-rule register recording calculations, thresholds, approval conditions, and exceptions, each traced to the code, the data, the named person, or the workaround it came from. A map of integrations and users recording what reads from and writes to the application and which roles depend on it, with each interface confirmed by an owner on the other side. And written success criteria naming the processes the replacement carries end to end, the reconciliation that must balance, and the conditions for switching the old system off.
From four sources, using a different technique on each. Read the code, because stored procedures, event handlers, macros, and save-time validation state what the system does rather than what people remember. Query the data, because distributions and gaps expose logic the code no longer contains. Interview the people, because intent lives with them, then validate each recovered rule against real cases before recording it. And catalog the workarounds, because a spreadsheet beside the application or an approval sent by email is a rule the system failed to carry and a requirement candidate for whatever replaces it, not a requirement until a real case shows the need.
Four causes recur, each one addressed directly by discovery. Rules found after the scope is signed arrive as change requests rather than requirements. Integrations counted as one system turn out to be several interfaces with separate formats, owners, and release calendars. Data cleanup deferred to migration becomes an unplanned project inside a planned one, at the point of maximum schedule pressure. And the operating model no one documented surfaces when real users meet software that implements the process as designed instead of as run. Each cause is cheaper to find before a scope is fixed than after it.
The inventories are counted rather than asserted, with row counts, key integrity, and interface owners verified. The business rules are recovered and traced to a source. The success criteria are written in terms someone will sign, including the reconciliation and the switch-off conditions. The data statement names what moves, what is corrected, what is archived, and what is abandoned. A risk list records what discovery could not resolve, because that list is what contingency is priced against. And the signatures are on the artifacts, from the business owner, the data owner, the interface owners, and IT.
Frequently yes, and the test is whether the team has three things: someone who can read the legacy code with authority, access to a data copy they are allowed to profile, and enough distance from the system to record how it behaves rather than how it was meant to behave. Two of the three is not enough on its own: whichever one is missing names the part to source, from outside or from inside once someone is given the access and the time. Internal teams hold an advantage on access and history and a disadvantage on distance, because the workarounds they live with are invisible to them. Where an outside pair of eyes earns its fee is on the rule archaeology, and on writing down the things everyone assumed were obvious.
Named signatures against named artifacts, with the meaning of each signature written above it. The business owner attests that the function inventory, the user and role map, the rule register, and the success criteria describe the system as it is operated. The data owner attests to the data statement, including the records deliberately left behind. Each integration owner attests to their own interface. IT attests to the data inventory, the integration inventory, and the risk list. A sign-off that says only "reviewed" is not a sign-off, because it commits no one to the description the estimate was built on.
Yes, enough that the two are separate exercises. Discovery aimed at a custom rebuild concentrates on recovering business rules, integration contracts, and data reality in detail, because the new system reimplements them line by line. Discovery aimed at a Power Platform build concentrates on process truth, whether the data model fits Dataverse, where delegation limits bite, what licensing the user population implies, and who owns the app after go-live. The inventory work overlaps. The judgments do not, and running the wrong one produces a scope aimed at the wrong destination.
Harden, rebuild, or retire is an architecture call with real money on every branch. i3solutions' senior application architects work with IT leaders who want that call made on evidence and carried into delivery.
Request an Application Scoping Discussion
US-Based | Est. 1997
© i3solutions. All rights reserved.
US-Based | Est. 1997
© i3solutions. All rights reserved.


